Human-in-the-Loop Review for Agent Eval Calibration
Humans catch the systematic biases that automated eval metrics accumulate over time.
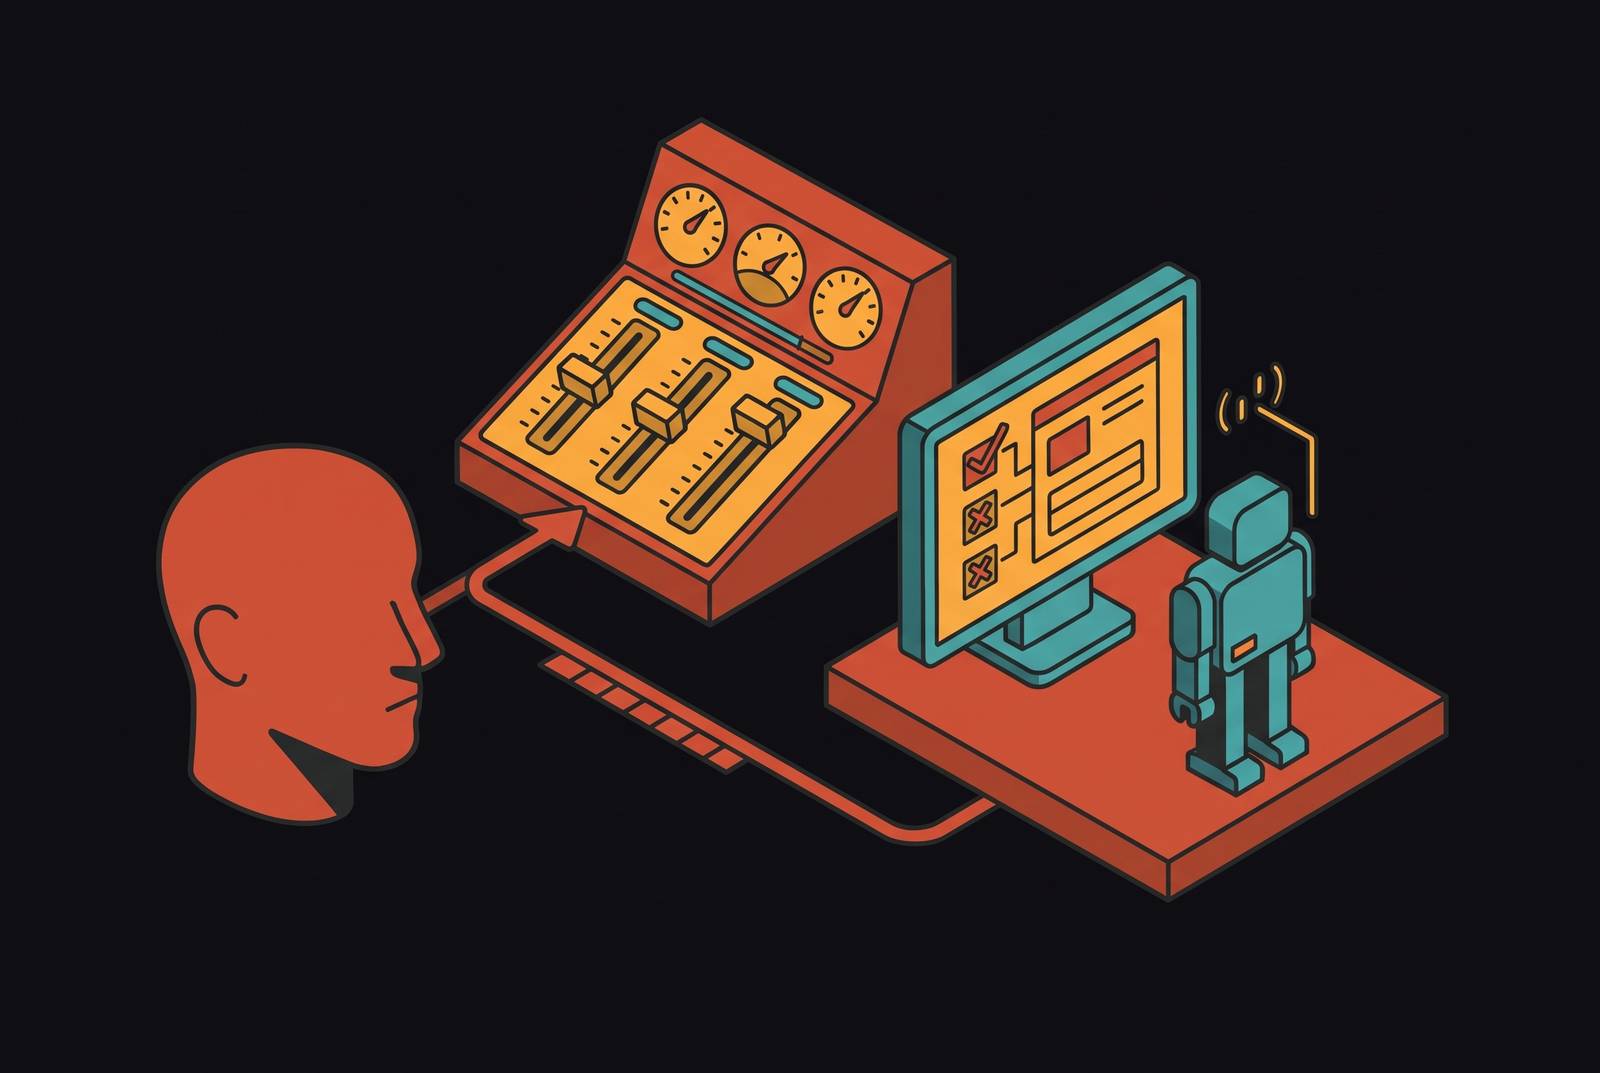
Human-in-the-loop review earns its place in agent evaluation not by replacing automated scoring, but by keeping automated judges honest. It is the mechanism that catches the systematic blind spots that cause eval metrics to drift silently away from what production traffic is actually doing to the system.
Why automated evaluation scores drift away from production reality
An eval score measures how well a system performed against the distribution of inputs the rubric was built around, and that distribution stops matching reality the moment production traffic diverges from it. Static benchmarks and aggregate scores are snapshots, frozen at the moment someone wrote the rubric, and they hold no information about the intents, edge cases, and adversarial patterns that appear in live traffic weeks or months later. Without a structured way to feed those new cases back into the eval system, the gap between what the dashboard reports and what users are actually experiencing widens on its own, and the first sign is usually a fail rate that climbs for no reason anyone can point to. LLM-as-a-judge systems add their own layer of distortion: survey work on LLM judges catalogs biases tied to answer length, position in a pairwise comparison, and a tendency for judges to favor outputs that resemble their own style, and on specialized expert tasks the agreement between subject matter experts and LLM judges can be only moderate, falling well short of consensus in domains such as dietetics and mental health. Bavaresco et al. find that agreement between humans and LLMs varies widely depending on the dataset, the property being judged, and the expertise of the human annotator, and recommend carefully validating LLMs against human judgments before they are used as evaluators. The Fiddler HITL guide illustrates the practical consequence with the case of an insurance claims assistant that can post green scores on faithfulness and relevance while users keep escalating the same answers, because the response is grounded in the right documents and still wrong on what the policy actually intends. The automated metric and the production outcome are measuring different things, and nothing in the dashboard tells you that until someone looks at the actual traces.
Structural exposure of agents to silent eval drift
Agents make this problem worse because of how they're built, not just because they're more complex. A single-call LLM produces one output from one prompt, so a failure happens in exactly one place. An agent chains planning, memory, retrieval, reflection, and tool calls, and that layered architecture means a single error early in the chain can propagate through every decision downstream, compounding into a failure that looks nothing like its root cause by the time it reaches the final output. An eval that only scores the final answer has no way to see that the plan was derailed three steps earlier by a bad retrieval, or that a tool call silently corrupted the state the rest of the run depended on.
HAS-Bench, a 2026 benchmark from Wu et al., makes this concrete with a flight rebooking task. Run the task with a fully automated agent that has no clarification channel and no control channel, and it silently keeps the wrong cabin class and commits an unauthorized write, producing a final output that looks structurally complete, reads as a successful rebooking, and is in fact wrong on both policy correctness and safety. Run the identical task with human clarification, feedback, and control channels open: the agent gets the cabin class right and the write gets proper authorization. Same task, same model, opposite outcome, and an output-only eval would have scored the first run as a pass. HAS-Bench's broader design evaluates human-agent systems under configurable levels of human participation, across different interaction channels and persona policies, tracking not just whether the task completed but process-level behavior like clarification quality, feedback utilization, and control calibration. Across six domains, the results show human participation substantially improving task completion and failure recovery, though the size of the gain depends on when the human steps in, how, and through which channel. The lesson for eval design is direct: agent failures tend to start in the middle of a run, in a wrong tool selection or a bad handoff between sub-agents, and an eval that can't see those intermediate steps can't catch the failures that live there.
What human-in-the-loop evaluation does in an agent eval system
HITL evaluation is often described as humans reading outputs and labeling them good or bad, which is a fair description of annotation but misses what makes the practice worth doing at scale. Labeling traces without changing anything downstream produces a pile of opinions that nobody ever uses again. A genuine HITL workflow does three distinct things: it aligns metrics by comparing human scores against automated scores to find where they disagree, it reviews for missed failures that no existing metric was built to watch for, and it curates confirmed failures into permanent regression test cases. Fiddler's HITL guide states the operational goal: humans set the standard and surface the failure modes, and automated evaluators then apply that standard across the volume of traffic no human team could review by hand. That division of labor is the whole point. Humans are slow and expensive relative to automated scoring, so their time belongs on the highest-value task available, which is deciding what "correct" means and catching the cases where the automated judge gets that definition wrong, not on reviewing every production trace one at a time.
This needs to be kept separate from HITL runtime control, where a person approves or blocks an agent's action before it executes in production. That's a different mechanism solving a different problem, and conflating the two causes real damage on both sides: teams that confuse evaluation with control either bury their agents in approval gates meant to catch problems after the fact, or they skip rubric calibration because they believe the runtime guardrails are already doing that job. The rest of this piece is about evaluation, not runtime approval. The collapse from calibration mechanism into plain annotation tends to happen through a specific set of mistakes: reviewers who were never calibrated against a shared rubric, review queues that only pull failures and never sample successes, and reviewer corrections that get entered without version tracking so there's no way to use them in regression testing or audit them later.
Designing the rubric and calibration round before opening a review queue
Noisy human labels are almost always a symptom of a vague rubric. That means the order of operations matters: the rubric and a calibration round have to happen before the review queue opens, because a bad rubric guarantees the queue produces noise instead of signal. Fiddler's guidance on this is specific: pick three to six scoring dimensions that match the actual risk profile of the application, commonly task completion, factual groundedness, policy or safety compliance, and tone or helpfulness, and add tool-use correctness as a dimension for agents specifically.
The scale for each dimension should match what the dimension is actually measuring. Safety and compliance dimensions work best as binary pass/fail, graded one-to-five scales suit dimensions where quality trends matter more than a hard cutoff, and a short free-text field for root-cause notes turns a score into something a reviewer can act on later. Each dimension should map to a decision: does a failure here block shipping, does it just get monitored, or does it escalate to a subject matter expert. Before any of this goes live, write anchor examples for each score level, good, borderline, and fail, each with a one-sentence rationale explaining the call. Have at least two reviewers independently score the same set of traces against those anchors, then sit down and resolve the disagreements in a calibration session.
The agreement between those reviewers needs to be measured with a chance-corrected statistic like Cohen's kappa rather than raw percent agreement, because raw agreement can look fine even when reviewers are guessing. Kappa under 0.6 means the rubric itself needs rework, not more reviewers thrown at the same ambiguous categories, and anything under 0.7 is a sign the anchor examples aren't doing their job. Hashemi et al. found that humans frequently don't fully agree with each other on multidimensional rubrics, and that LLM predictions fail to track human judgment well without calibration. It's the signal that tells you which anchors need sharper definitions. The rubric itself should be versioned like code, with a rubric_id attached to every annotation, so a later change to scoring criteria is traceable and an untracked correction can't quietly corrupt a regression suite that depends on consistent labels. And the queue needs to pull successes as well as failures, because calibrating what "good" looks like is just as necessary as cataloging what "bad" looks like.
Reviewing full execution traces instead of final answers
Once the rubric is set, the review itself has to work on the full trace, not the final answer alone, because a single error early in an agent's chain can propagate through every downstream decision until the failure signal no longer appears in the final answer. Anthropic's engineering documentation defines a transcript as the complete record of a trial, including outputs, tool calls, reasoning, intermediate results, and other interactions, and treats human graders as the reference standard used to calibrate model-based graders against those transcripts. That's the right unit of review for an agent: not the answer the user saw, but everything that produced it.
A usable trace for review needs to carry the prompt, the system instructions, the retrieved context, each tool call with its arguments, the intermediate reasoning spans, any sub-agent handoffs, the final output, and operational data like latency and token cost, all stitched into a single hierarchical record a reviewer can step through. Confident AI's review model requires annotators to score not just the final response but the traces, sub-traces, spans, tool calls, and multi-turn threads underneath it, because agent failures cascade from those intermediate steps rather than announcing themselves in the output. Each field in that trace corresponds to a layer where a specific kind of failure can be isolated: the retrieved context shows whether the agent had the right information, the tool call arguments show whether it used that information correctly, and the handoff points show whether a sub-agent passed clean state to the next step or corrupted it along the way.
None of this works if the review interface requires engineering skills to use. Subject matter experts, QA staff, and domain reviewers need to reach these intermediate steps directly, without writing code to extract them, and building that access is an engineering responsibility rather than a cosmetic nicety. Whether a no-code review surface exists is what decides whether non-engineers can take part in review at all. The payoff of doing this well is root-cause attribution: reviewing at the step level, asking specifically whether the planner chose the right tool at a given point, turns a vague "the agent got it wrong" into a concrete, actionable finding the engineering team can actually fix.
Using human-automated disagreement to find where judges are systematically wrong
Once reviewers are scoring full traces against a calibrated rubric, the most useful output is the pattern of where human scores and automated scores disagree, because that pattern points directly at where the automated judge is producing false confidence. One calibration heuristic works like this: pull a sample of recent outputs, have a domain expert score them against the same rubric the automated judge uses, then compare the two sets of scores directly. If agreement falls below a clear threshold, the automated scorer needs work, and that comparison is what keeps the automated eval system honest over time rather than letting it drift unchecked.
The clusters, not the one-off disagreements, carry the value: a judge that consistently over-scores verbose answers, or consistently misses policy violations concentrated in one domain, is actively misrepresenting production quality in a specific, identifiable direction. It's producing a metric that actively misrepresents production quality in a specific, identifiable direction, which is worse than having no metric at all because it creates false confidence. A metric alignment workflow that tracks human annotations against automated scores, broken down into false positives, false negatives, and per-metric agreement rates, tells a team exactly which of its automated metrics can be trusted and which ones are reporting numbers nobody should be acting on.
From there, failure clustering turns individual disagreements into structural findings: the confirmed failures are grouped by pattern, tool errors, retrieval misses, policy violations, to find the categories no existing metric is catching. Those categories are candidates for a new automated metric built specifically to watch for them. Over enough review cycles, the human decisions accumulate into training data that sharpens the automated evaluators themselves, and the loop reinforces itself: a better rubric produces better labels, better labels produce better-calibrated judges, and better-calibrated judges surface sharper cases for the next round of review. A backlog that keeps growing means the loop is breaking somewhere, and the fix is either lowering the threshold that auto-flags cases for review or adding reviewer capacity before the gap widens further.
Building and refreshing golden sets from reviewed production traces
A golden set assembled from synthetic or hand-written test cases encodes whatever the people who wrote it imagined failure would look like. A golden set built from reviewed production traces encodes the failures the agent actually produced, under real traffic, with all the messiness that synthetic cases tend to smooth over. That difference matters because it changes what the golden set is for: instead of a fixed snapshot meant to catch regressions against an imagined worst case, it becomes a living record that grows every time a human reviewer confirms a new failure the system hadn't accounted for.
This is the direct continuation of the curation step described earlier in the HITL workflow: confirmed failures, once reviewed and scored against a calibrated rubric, get folded into permanent regression coverage rather than discarded after the review session ends. Each new category of failure uncovered through disagreement clustering, whether it's a cluster of tool errors or a recurring policy miss in one domain, becomes a new entry the regression suite checks against on every future model or prompt change. The golden set grows in step with however the production traffic is actually changing, and when the rubric itself gets a version update, the traces tied to the old version stay traceable rather than quietly going stale. An eval system built this way doesn't catch yesterday's failures. It carries them forward, permanently, against whatever gets shipped next.