Least Privilege Access Design for Agent Tool Permissions
Enforce agent permissions outside the model's reasoning loop.
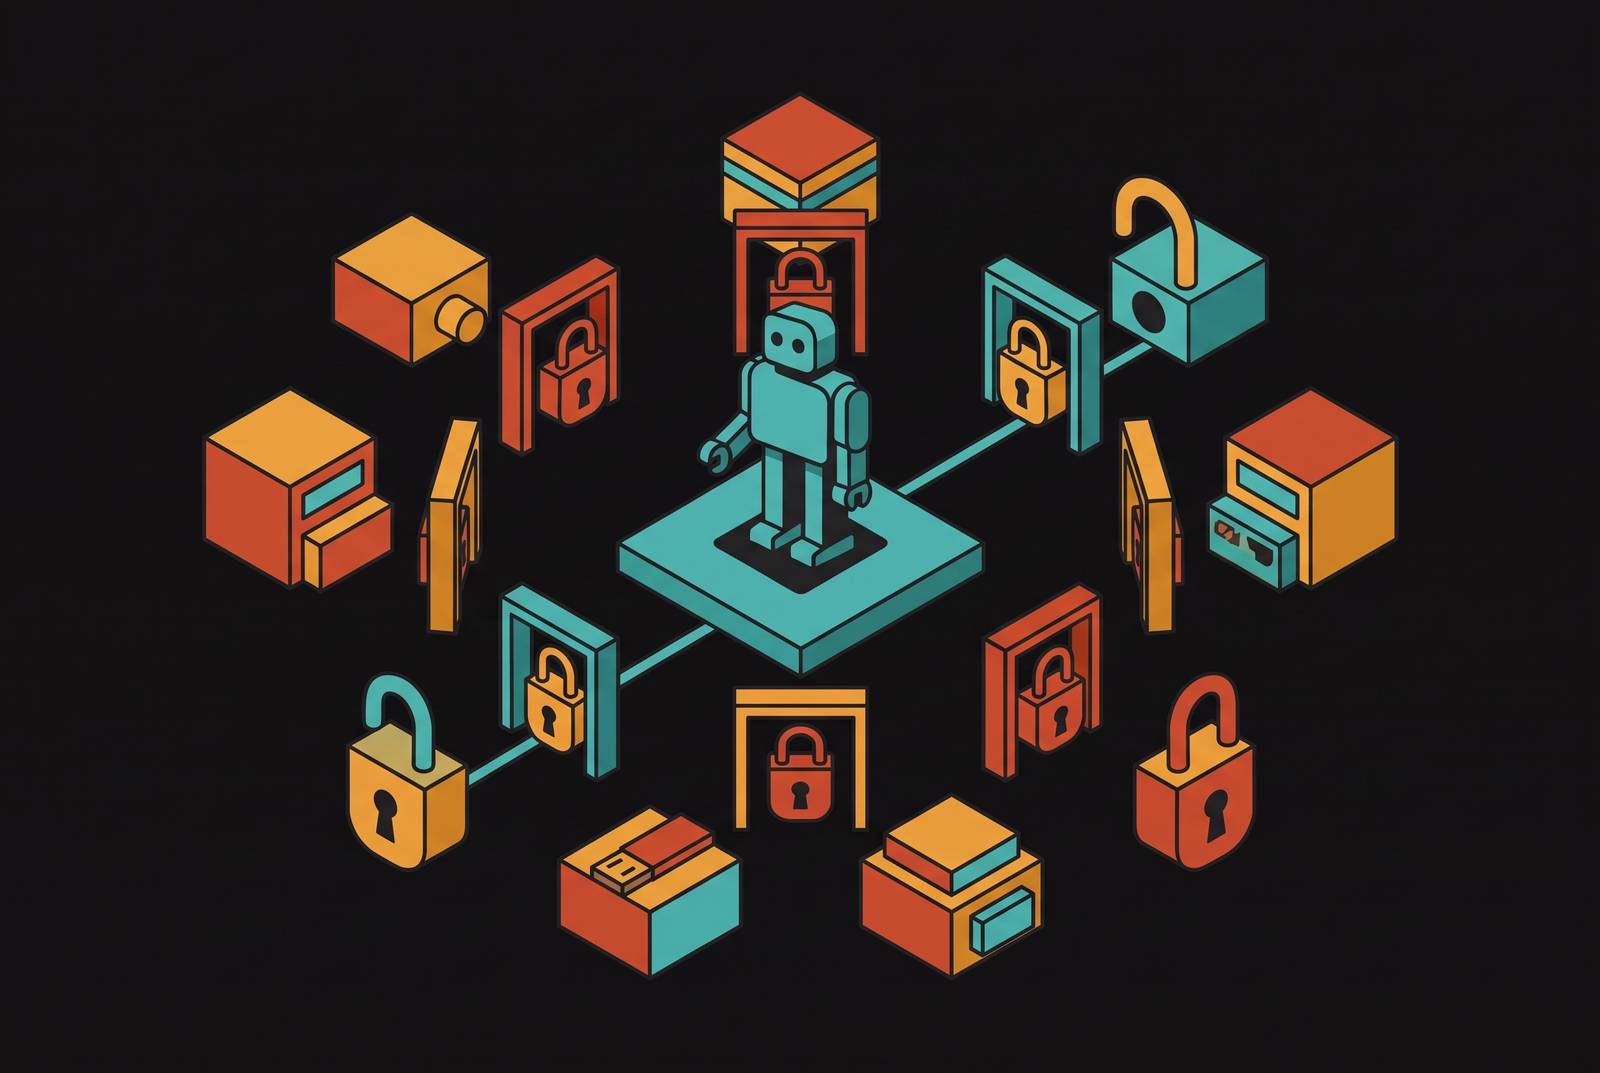
Least-privilege access design for agent tool permissions is a harness engineering problem. The boundary must hold even when the model takes the wrong action. That requires engineers to scope tools to the task, bind credentials to those tools, and enforce access outside the model’s reasoning loop, then use production traces to detect when those boundaries erode.
Why tool permissions for AI agents cannot be enforced by the model or the prompt
A common deployment pattern begins with an engineer’s token and ends with a prompt caveat such as “please do not delete anything”. The agent operates as a single principal with broad access to connected tools and data, although its task needs only a narrow slice. The caveat changes what the model is asked to do, but it does not change what the credential permits.
An instruction inside the model’s context cannot serve as an independent check on the model’s decisions. Microsoft recommends treating each agent as a first-class principal with a lifecycle-managed identity, explicit roles, and tightly scoped tool access. Permission enforcement must sit outside the reasoning loop, where an attempted action can be denied regardless of how the model justifies it.
What least privilege actually means for an agent, and where the principle breaks down without adjustment
The principle of least privilege says that every program should run with only the access it needs to do its job. That restriction limits the blast radius of an accident, error, or compromise. For a conventional program, the required access is readable from its code. An LLM agent instead decides at runtime what to do next, and those decisions change with the prompt. Inspecting the code cannot reveal all the ways the agent might use tools.
For an agent, the principle of least privilege, or POLP, needs the complementary lens of the principle of least authority, or POLA. POLP asks what a program is permitted to access. POLA asks what effects it can cause, including through other programs it calls. Consider an agent inside a container with no direct network access but with a fetch_url tool on an MCP server outside that container. Even with the container’s block on direct network access, the tool lets the agent fetch any URL.
The distinction becomes more consequential if the same server holds a GitHub token that can push to every repository in the organization. The agent never sees the token, but it remains one tool call from production code. Prompt injection can use that gap when instructions hidden in a web page, email, or retrieved document lead the agent to do things the user never intended. Permission design must therefore examine each tool’s declared inputs and outputs and its reachable effects. It must also account for effects that become possible when tools are combined.
How the agent's architecture determines where permission boundaries can actually be enforced
Three architectural layers determine where those effects can be constrained, namely identity and role assignment, the planning-time tool manifest, and server-side validation during execution. Identity establishes whose authority is being exercised. The manifest limits which tools are available for the current task. Server-side validation decides whether a particular call is allowed. These controls answer different questions, so none can replace the others.
Identity comes first because the remaining controls need an unambiguous principal. Microsoft identifies failures involving inherited engineer tokens and unclear mixtures of agent identity and delegated user scope. A dedicated agent principal needs a named owner, an explicit purpose, and its own lifecycle. Role-based access control then sets the access ceiling. The SAP/Oxford plan-then-execute paper describes assigning role identity during planning and enforcing it during execution, so a DataReader role cannot invoke write or communication tools.
Task-scoped assignment narrows that role ceiling by loading only the tools needed for a particular execution. The 2026 Singapore Consensus extends this approach to capabilities that adjust with the current task and context. At execution time, the MCP server is the policy enforcement point. The MCP specification requires servers to validate tool inputs and implement access controls, and allows the returned tool set to vary with the caller’s authorization. The manifest can therefore reflect granted scopes rather than presenting an unrestricted catalog that the model is expected to police.
Designing the narrowest tool manifest a task actually requires
Microsoft documents a scope-creep pattern that starts with an apparently read-only use case and a broad role. As the workflow expands, write access is added without reconsidering the role design. The resulting over-provisioning is rarely revisited. Enumerate the minimum actions required, then build the manifest upward from those actions.
That assessment must include combined authority. Email, files, a ticketing system, and a code repository can each appear low-risk in isolation, while their combination allows cross-system correlation and actions no one authorized as a whole. Read and write tools should be kept clearly separate, with no single schema that bundles them together. CrewAI’s declarative scoping provides a concrete pattern by assigning tools per agent role at definition time and allowing task-specific overrides. The effective declared set is a structural limit, with a ToolNotFoundError when the executor attempts to invoke a tool outside it.
SkillScope, from a university research team and collaborators at ACM CCS 2026, makes the task-conditioned nature of this problem explicit. The same action can be legitimate under one prompt and over-privileged under another. A skill cannot therefore be judged adequately by a static permission set detached from the request it serves. SkillScope validates thousands of skills with over-privileged behaviors in the wild and reduces triggered over-privileged action instances by 88.56 percent while preserving legitimate task completion. Its result supports automated task-conditioned checking when designing the manifest, with success judged by both how much authority is limited and whether the work gets done.
Binding credentials to tools, not to the agent, and why that changes auditability
With a single powerful API key, every tool path has the same broad credential boundary. Its scope determines the blast radius of a failure, compromise, or unintended action, making narrower controls harder to enforce. The agent should hold no credentials, while each tool should hold its own credential scoped to its required permissions. Under that arrangement, a failure in one tool does not confer credential access to the others.
This separation does not remove the need for a dedicated agent identity. Tool credentials determine what an integration can do, while agent identity establishes whose action is being authorized. Microsoft recommends assigning the agent its own identity so that its actions can be attributed and its identity revoked without affecting other systems. An unclear mix of agent identity, delegated user scope, and shared service accounts gets in the way of that goal. Logs may record a tool call without establishing who authorized it, under what role, or within which intended scope.
During an incident, the missing relationship between identity and authority prevents clear answers to customers or auditors even when the tool activity is visible. Credential binding makes that relationship more precise by separating the agent’s identity from each tool’s access. Microsoft also recommends time-limited credentials. A credential that expires when the task scope closes cannot be replayed in a later session, reducing standing access beyond the work that justified it.
Enforcing tool boundaries at the execution layer, where they cannot be talked around
Plan-then-execute architecture separates the component that reasons about a task from the component that performs it. The SAP/Oxford paper describes a Planner that produces a structured plan artifact and an Executor that follows it step by step. The Executor does not re-reason from raw user input and needs only the tools required for its plan steps. In this design, the pre-approved plan forms a control-flow boundary that prevents injected instructions found during execution from authorizing calls outside it.
That boundary still needs server-side enforcement. Each call must be validated against the agent’s granted scopes, rather than accepted on the strength of client consent or the agent’s stated intent. The University of Connecticut LASM survey found that principal trust inversion was the root cause of every tool execution layer attack it surveyed. Its non-transferability finding states that a control at one layer has zero detection power against an attack localized at another.
High-impact, irreversible actions need a further structural gate. The SAP/Oxford paper describes Human-in-the-Loop verification for pre-identified steps that cannot be undone, and OWASP recommends human approval together with minimal permissions. Prompt Flow Integrity research looks at how to limit which prompt content may affect which execution paths. This emerging approach extends integrity controls to prompt routing, but it does not replace the core tool-layer checks.
How silent failures and schema drift erode tool boundaries that looked correct at deployment
A tool can fail while returning HTTP 200 with an empty payload. No error appears for review, and the agent continues as though the tool worked. Silent failure is especially damaging when later work needs output that is missing from what looks like a successful response. A permission design that looked correct at deployment does not protect against that mismatch. Its continued validity depends on the tool, its registration, and its behavior remaining aligned.
Schema drift breaks that alignment when a tool changes but its registration does not. The model then calls against a schema that no longer matches what the server expects. Description drift can be quieter still, causing the model to call a tool in the wrong situation or omit it when needed without producing an error. Permission drift follows a related pattern as workflows expand and write access accumulates without renewed review.
Production traces provide the signal needed to detect this erosion. The SAP/Oxford paper and related work locate multi-component behavior in the interaction among stages. A valid response with an empty payload becomes intelligible as a failure when the later steps that relied on it are examined. Likewise, evaluating permission use requires seeing the sequence of calls in the context of the task.
Treating permission enforcement as an ongoing engineering discipline, not a deployment checklist
Trace evidence is useful only when it leads to a diagnosis at the responsible layer. A wrong tool in the manifest, an over-broad credential, and schema drift are harness failures that require harness fixes. Labeling each outcome generically as agent failure obscures the mechanism. Retraining the model does not remove an excessive credential grant or repair a stale registration. Attribution must identify the boundary that failed before a change can address its cause.
Removing a tool or narrowing its scope changes the actions the agent can reach, including actions on which a working workflow may depend. Replay against production traces tests whether the new constraint preserves legitimate task completion. SkillScope’s result demonstrates why that second condition matters, since reducing over-privileged actions is not enough if authorized work also stops.
Tool permissions belong to the harness with prompts, memory, and workflow logic, and deserve the same rigor as code review and testing. That means evidence-backed changes, reviewable diffs, and validation against real production traces before shipping. It also means treating traces as an ongoing signal of boundary erosion rather than material consulted only after an incident. Deployment establishes the initial boundary, but production behavior reveals whether that boundary still matches the task.
Sources
- Architecting Resilient LLM Agents: A Guide to Secure Plan-then-Execute Implementations
- A Systematic Survey of Security Threats and Defenses in LLM-Based AI Agents: A Layered Attack Surface Framework
- The 2026 Singapore Consensus on Global AI Safety Research Priorities
- SkillScope: Toward Fine-Grained Least-Privilege Enforcement for Agent Skills
- Prompt Flow Integrity to Prevent Privilege Escalation in LLM Agents
- Least privilege for AI agents: Identity, access, and tool binding