Eval Metric Selection for Multi-Step Agent Task Quality
Measure agent traces at the layer where they break, not at the final response.
Priya Subramaniam
Senior Staff Writer
Priya spent eight years as a reliability engineer at a mid-sized fintech before moving into technical journalism, where she now covers the systems and signals behind AI agent breakdowns. Her writing focuses on diagnosing root causes in production environments, with a particular emphasis on observable failure patterns.
7 stories
Measure agent traces at the layer where they break, not at the final response.
Traces preserve the causal chain that flat logs miss entirely.
Prompt injection succeeds because agents can't separate instructions from retrieved data.
Attribution determines whether to fix the model or its surrounding systems.
Model failures usually stem from the harness scaffolding, not the AI itself.
Fingerprints in execution traces reveal why production agents get stuck in loops.
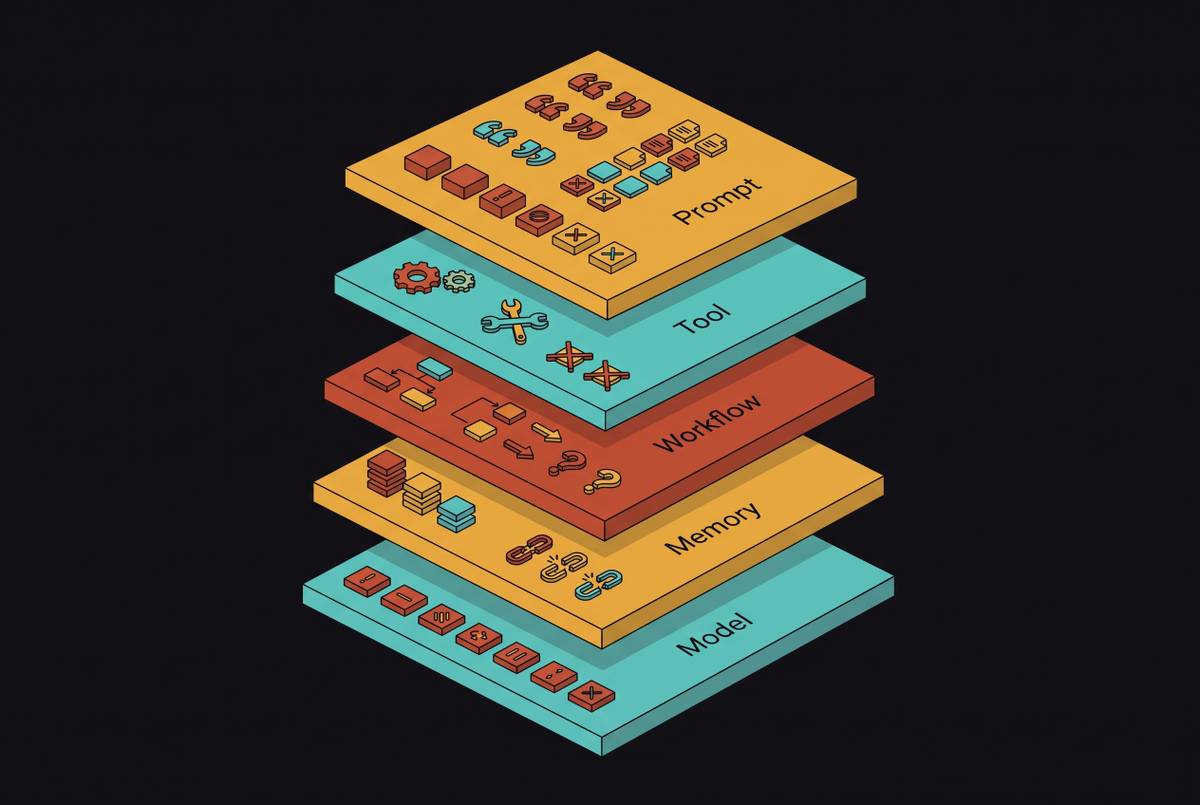
Four pipeline layers, four distinct failures—misdiagnosis is why fixes don't work.