Eval Metric Selection for Multi-Step Agent Task Quality
Measure agent traces at the layer where they break, not at the final response.
A support agent calls the refund tool on the wrong order, and the reply it generates reads perfectly: "Your order has been canceled." Scored against a reference sentence, that output earns a high mark. The customer, meanwhile, has been refunded for the wrong purchase. That gap, between what a sentence-level score says and what actually happened, is the starting problem for anyone trying to measure whether a multi-step agent is working.
Metrics for multi-step agents that follow the trace, not the final output
Grading an agent by its last message is like grading a surgery by the patient's parting handshake. LLM evaluation and agent evaluation share tools and vocabulary, but they are not the same discipline. An LLM eval checks if one turn of text is accurate, fluent, or well-formed. The unit worth measuring is the trace, the full ordered record of observations, decisions, tool calls, and results, which captures what the sentence sitting at the end of it cannot.
The refund example makes the stakes concrete, but you see the same blind spot with any metric built for text comparison. BLEU, ROUGE, and BERTScore measure overlap between words or embeddings. They have no way to represent a tool call or a planning decision, so when they're pointed at an agent trace, they return numbers that look rigorous and mean nothing about whether the agent did its job. LLM-as-Judge setups built around fixed categories like Helpfulness, Fluency, and Safety run into a related wall. Those dimensions were built to grade chat assistants on a single reply, and a rubric shaped that way has no way to ask whether the agent's path to the goal made sense. A fluent, helpful, safe sentence can still sit at the end of a broken sequence of tool calls.
Breaking the agent's run into spans turns this into a mapping problem. An agent's run has to be broken into spans, and each span needs a metric suited to what that span was actually responsible for doing.
How the harness layers map to distinct failure modes
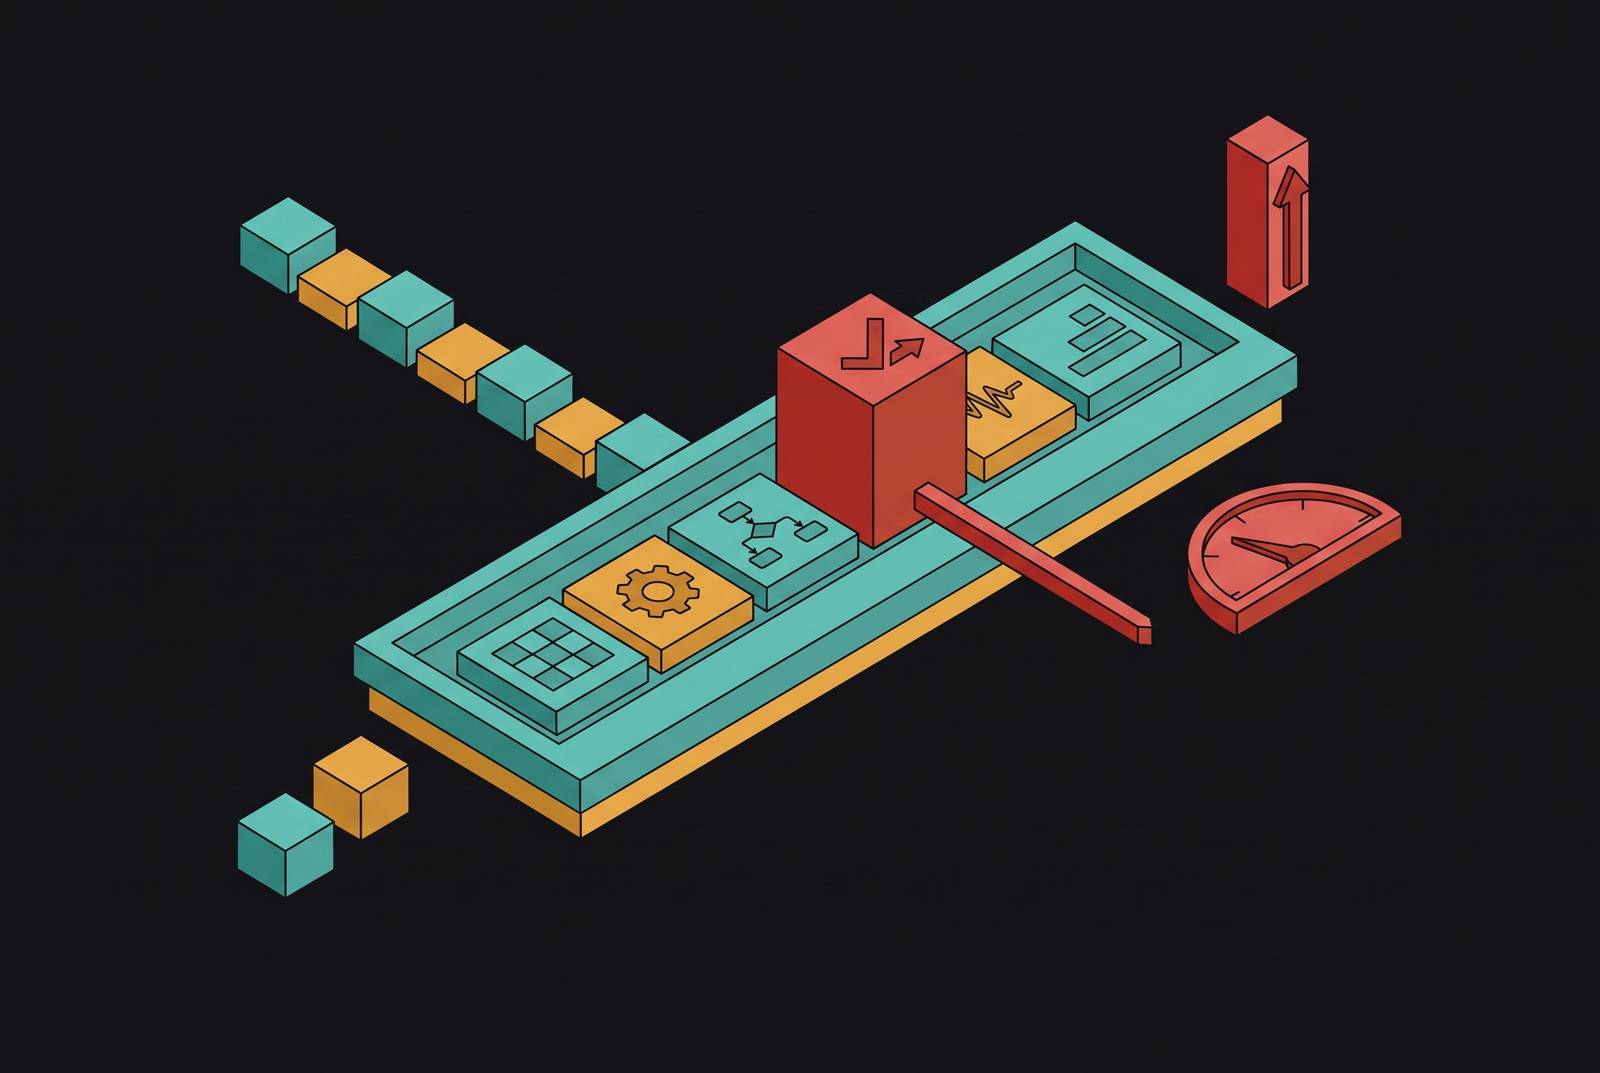
A harness underlies any multi-step agent, built from distinct layers: the prompt that frames the task, the tools the agent calls, the workflow logic that sequences those calls, and the memory that carries state from one step to the next. Each layer breaks in its own characteristic way, and that's the reason a shared rubric applied across all of them misses most of what goes wrong.
A prompt failure looks like inconsistency: run the same task twice and the agent picks different tools or follows a different line of reasoning each time, because the instructions didn't pin down enough to produce the same behavior on repeat. A tool-layer failure looks different again: the call is shaped correctly, but it's wrong underneath, carrying a field the live API no longer recognizes, a type mismatch, or a parameter name the agent invented. The workflow layer fails behaviorally rather than semantically: the agent gets stuck retrying a step, keeps invoking tools without converging on a decision, or asks the user for clarification instead of applying a safe default or escalating. Memory fails when context built up over earlier steps turns stale, gets truncated, or gets flatly contradicted by something a later tool returns, because then the agent keeps acting as if the earlier version were still true.
None of these are variations on one underlying problem. These are four separate failure modes, and each comes from a separate part of the system, so each one needs a metric built to catch it specifically. Agent execution doesn't run as a straight line either: tools call other tools, a single LLM call can branch into parallel paths, and retry logic can build out an execution tree with real depth. If you want to debug that structure, each decision point needs visibility as its own span. Choosing a metric starts with answering one question: which layer is this span even testing?
Metrics for the tool layer: measuring call correctness at the argument level
Tool calls fail in ways that are invisible from the outside, because a malformed call and a well-formed one can look identical until something downstream chokes on it. That's why each tool call has to be scored as its own span, checking which tool got selected, whether the arguments match the current schema, whether required fields are present, whether the sequence of calls reflects a plan that makes sense, and whether the agent chose the right tool for the step, passed arguments that match the live schema, and followed a defensible plan across its sequence of calls.
The clearest version of this failure looks almost too simple to cause real damage: an agent passes every happy-path eval in staging, then breaks the moment it reaches production, because one argument name changed from customer_id to account_id on the live API. The LLM was prompted against the old schema. Nothing about the call looks obviously wrong to a human skimming the trace, and an eval built around whether the final response reads well will not catch it either. Metrics like faithfulness and relevance, built for retrieval-augmented pipelines, run into the same ceiling: they were designed to judge whether a generated answer is grounded in retrieved text, and they have no way to evaluate whether the agent called the right tool with the right arguments. Applied to tool-using agents, they produce confident-looking scores that say nothing about the thing that actually broke.
Argument correctness has to be checked directly and explicitly, because without that check, the failure only becomes visible once a downstream step receives a malformed result, and the agent either retries forever, driving up cost, or halts. Trajectory match extends this from a single call to the sequence: it compares the agent's actual path of tool calls against a reference path, using exact, in-order, or subset matching depending on how strict the comparison needs to be. That method is reference-based by design, so it depends on having a labeled correct path to compare against, which costs real effort to produce at scale. Where no fixed reference exists, a reference-free LLM-as-judge evaluator can assess whether the logic of a sequence holds up on its own terms. What makes rule-based checks, like schema validation and tool-call verification, the right instrument at this layer is that they're deterministic. A required field is either there or it isn't. A type either matches or it doesn't. There's no judgment call to make, which is exactly the property this layer needs.
Metrics for the prompt layer: detecting ambiguity through determinism and reasoning coherence
Prompt quality is visible only across multiple runs, not in any single one. If you run the same task against the same agent five times, an ambiguous prompt will produce five somewhat different tool selections and reasoning paths, even when nothing else about the task changed. That variance is the signal that the prompt underspecified the task. Low determinism, the same task producing different behavior across repeated runs, is the diagnostic to look for.
Reasoning coherence metrics check something narrower but related: whether the agent's stated reasoning at a given step is actually consistent with the information it had available at that point. This catches cases where the prompt left the agent without enough grounding to reason from, so the agent fills the gap by inventing a rationale that sounds plausible but doesn't connect to anything real in the trace. Because this judgment is semantic rather than structural, it needs an LLM-as-Judge approach rather than a rule-based check, but that judge has to be calibrated against human labels first. An uncalibrated judge can end up carrying the same ambiguity as the prompt it's supposed to be grading, which defeats the purpose. MLflow's approach to judge alignment uses algorithms including GEPA and MemAlign to optimize judge prompts against human-labeled examples, so the automated score tracks what human reviewers actually flag rather than drifting on its own.
Prompt-layer metrics earn the most value when tracked over time rather than read as a single snapshot. A prompt that produced consistent behavior last month can turn flaky after a model update, even with the prompt text unchanged, and that shift signals model drift that tool-layer or workflow-layer metrics won't surface on their own.
Metrics for workflow sequencing: identifying loops and stalls before they reach the user
Workflow failures don't look like bad content. An agent stuck in a loop can produce individually reasonable tool calls and individually coherent reasoning at every step, and still never converge on an answer, so you won't catch it with an output-quality metric or a reasoning-coherence metric. The failure is behavioral, visible only in the shape of the execution graph, not in any single span read in isolation.
Three structurally distinct loop types occur at this layer, and each needs its own detection logic. A retry loop repeats the same step without making progress toward the goal. A tool loop keeps the agent calling tools indefinitely without ever reaching a decision point. A clarification loop has the agent repeatedly asking the user for more detail instead of escalating to a human or falling back on a safe default. Catching all three requires looking at the structure of execution, not the content of any given message, and because agent execution can branch into parallel paths with tools calling other tools, debugging cascading failures requires visualizing the graph itself. A linear trace, read top to bottom, won't show where a loop actually started.
A common trigger for this category of failure sits outside the agent's own logic entirely: an external API returns a schema the agent wasn't built to parse, the agent can't make sense of the result, retries the same call, and lands in a loop that neither a prompt-layer eval nor a tool-call eval was built to catch, because the failure originates in workflow coordination, not in the call itself or the reasoning behind it. A related failure occurs when accumulated context pushes tool definitions out of the active context window, so the agent loses access to tools it needs partway through a run and stalls or loops as a result. Catching that requires tracking context utilization across the whole trace. The complement to all of this is termination quality: whether the agent actually reached a well-formed stopping point, goal achieved, safe default applied, or an explicit escalation, rather than simply running out of steps. Step count alone can't tell a stall apart from an efficient early exit, but termination quality can.
Metrics for the memory layer: catching stale and contradicted state across turns
Picture an agent that writes a state to memory early in a run, a later tool result contradicts it, and the agent still acts on the earlier version because that's what it retrieved first or weighted more heavily. The final answer looks like bad reasoning. The actual cause sits several steps earlier, in a memory write or retrieval that went wrong before the reasoning step ran.
This is the hardest failure mode to catch with standard metrics, because it appears as an outcome problem at the exact moment it is really a retrieval problem. Measuring it means checking state consistency across turns: whether the agent's working assumptions at a given step are coherent with everything it had access to up through that step, which is a stricter check than whether the final answer lines up with the last tool call made. Research on agent memory systems backs up how hard this specific capability is to build. A benchmark built around 234 multi-session scenarios, designed to test whether memory systems track evolving state rather than just recalling facts, found this kind of state tracking difficult for existing memory systems, retrieval-augmented baselines, and long-context baselines alike. A state-first method built to explicitly track when facts get superseded substantially improved current-state accuracy over the strongest same-backbone baseline on one model, and over the strongest memory system on another, showing how far off the default approaches start.
The step where a memory failure becomes visible and the step where it actually originated are often separated by several spans in between. Attributing the failure to its real cause means tracing it back through the whole execution graph, not stopping at the step where the bad output showed up. A metric that only looks at the final output, or only at the step where things visibly went wrong, can never trace a failure back to the memory layer. Only a metric built to track how state propagates across the entire trace can do that.
Span-level scoring and root-cause attribution
Metrics built for each layer tell you that something broke. They don't, by themselves, tell you which span actually broke it, and without that attribution, nobody knows which team or which fix the problem belongs to.
Consider how a single error moves through a trace. A tool-layer schema mismatch produces a malformed argument. That malformed argument becomes a malformed input one layer up, in the workflow logic. The workflow logic, unable to parse what it received, triggers a retry loop. By the time anyone looks at the trace, what they see is a loop, a workflow-layer symptom, and if the fix stops there, the agent stops looping, but the schema mismatch that caused it in the first place is still sitting in the tool layer, waiting to cause the same failure again under slightly different conditions.
Root-cause attribution means finding the first point where execution diverges from a correct path and tracing responsibility to the actual component behind it, whether that's the model, the prompt, a tool, the workflow logic, or memory, rather than stopping at wherever the failure happened to become visible. You need four layers, each with metrics built to its own failure mode, to have this foundation. Attribution is what turns that foundation into something a team can act on: not just a signal that a run failed, but a pointer to the exact span, and the exact layer, where the fix actually needs to go.