Scoring Observability Platforms on Harness Layer Granularity Across Prompt Tool Workflow and Memory
Evaluate observability platforms on whether they pinpoint failures to specific agent layers.
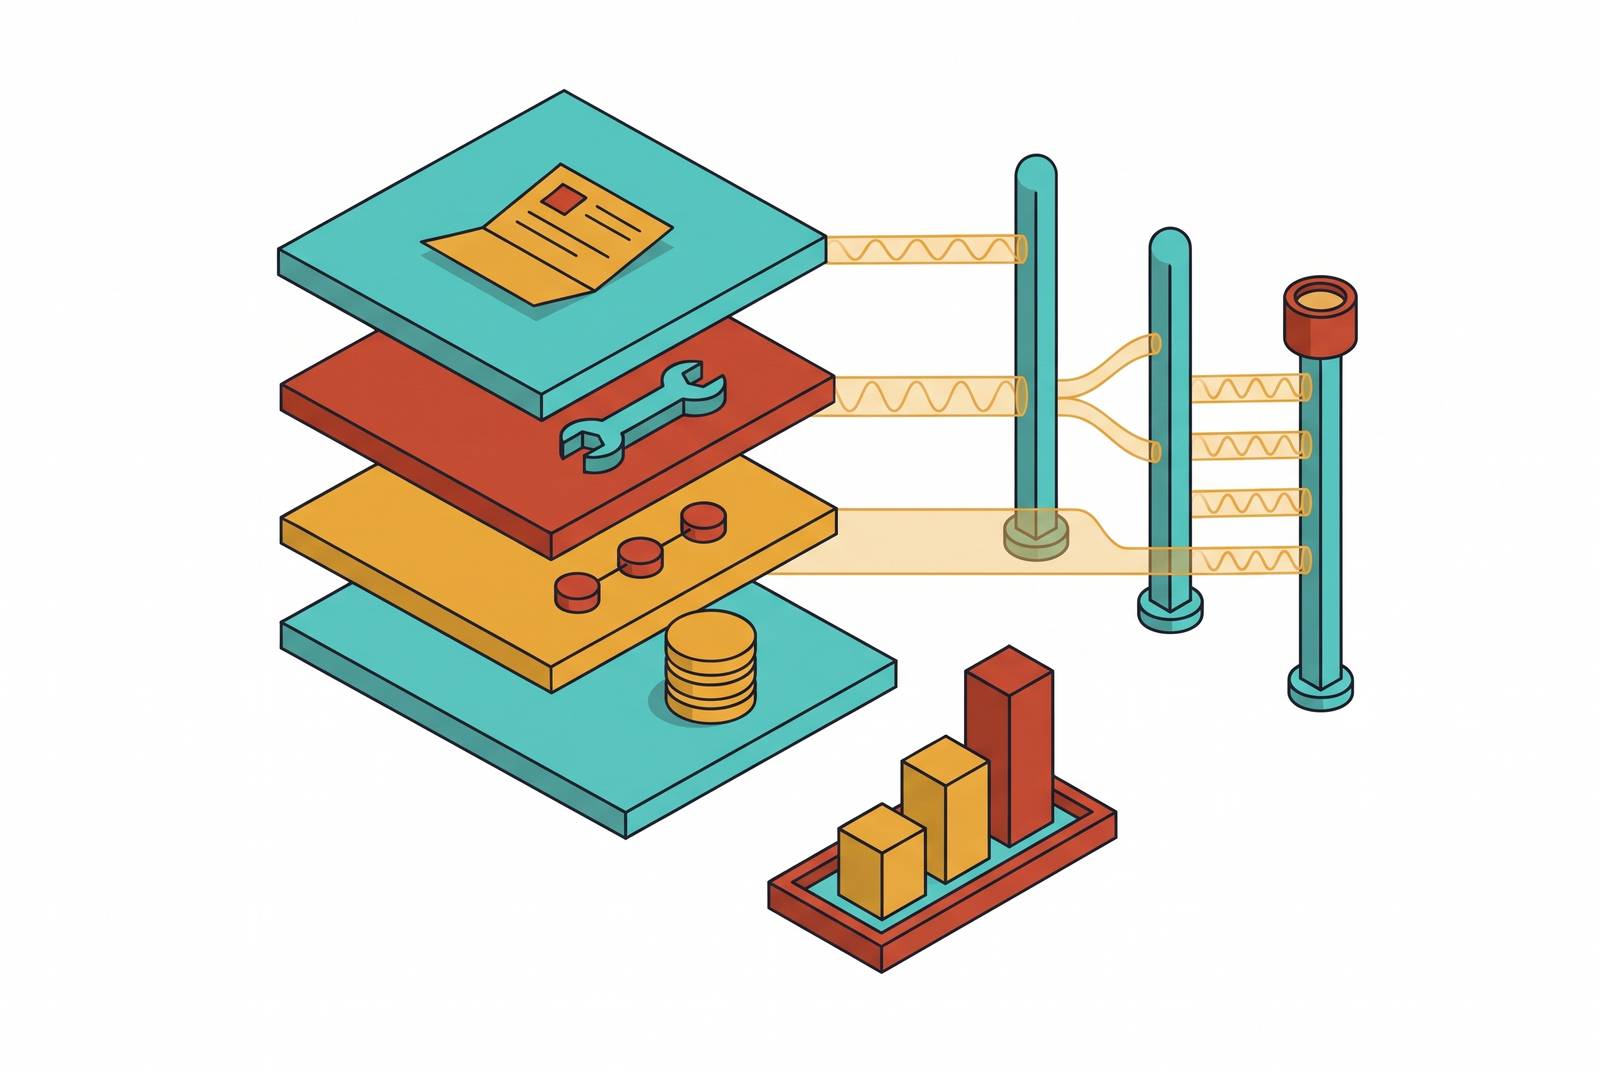
AI agent failure attribution by harness layer requires separate evidence for prompt, tool, workflow, and memory failures. This article develops a framework for scoring observability platforms on whether they capture each layer’s artifacts, identify the cause, and expose evidence an engineer can use. The decisive test is whether a platform distinguishes where an error appeared from which layer caused it.
Why “the run failed” does not tell you which layer caused it
An agent completes its trace, the run is marked failed, and an engineer faces a wall of spans with no clear owner. The sequence shows calls, responses, and timing, but the cause remains unresolved. A tool exception could come from an outdated argument expectation, while a wrong answer could come from stale retrieved context. The failure flag records the run’s outcome.
Production agents have several layers, and a fault in one can cause an error elsewhere in the run. Flattening their execution into an undifferentiated stream obscures those boundaries and leaves the engineer to reconstruct them. In that gap, the prompt becomes the default repair target because it is accessible. Yet changing instructions cannot fix every broken tool contract or remove a wrong fact from persistent memory. Remediation starts with guesswork when the trace cannot establish ownership.
Why harness layers fail differently and need different signals
Ambiguous instructions can produce hedging, hallucination, or the wrong action even when the LLM call completes successfully. Finding the fault means comparing prompt content with the model’s output, and finding prompt drift after a model update also calls for version-level attribution.
Tool failures concern the contract between an invocation and its result. With schema drift, arguments that were valid can be rejected, while a silent wrong-value return can provide stale, out-of-range, or incorrectly scoped data without an exception. Status alone cannot show whether a call succeeded or had a semantic failure. The relevant evidence is the argument payload, the schema in force, and the returned value.
Workflow failures instead concern execution structure. A loop, premature exit, or wrong branch becomes intelligible through step sequencing, invocation counts, and the conditions governing progression. Memory failures concern the context supplied to generation and its lineage. Irrelevant retrieved content requires inspection of the chunks, while incorrect facts persisting across sessions require a link to the run that wrote them. These distinctions determine what instrumentation must preserve.
What a scoring framework for per-layer granularity needs to measure
An engineer evaluating a platform needs answers to four questions. First, does layer isolation make prompt, tool, workflow, and memory distinct, queryable entities, or must their identities be inferred from tags? Second, does artifact fidelity keep the evidence that each layer produced, along with its timing and status? Third, does failure attribution show which layer caused the fault and what went wrong? Finally, does actionability provide an inspectable artifact that supports a concrete change?
These criteria separate visibility from diagnostic usefulness. A recorded retrieval event establishes that retrieval occurred, but not whether its content was stale. A failure label names a symptom unless the platform exposes the evidence behind it. A platform can also store a payload without correctly tracing the failure to its cause. Capture and attribution need separate scrutiny.
The scoring scale is absent, partial, and complete. Absent means the platform does not have the evidence from that layer needed to diagnose a fault, even if it records infrastructure signals. Partial means it exposes some relevant evidence but leaves gaps in capture, attribution, or review. Complete means it isolates the layer, preserves its required artifacts, explains failures, and exposes evidence an engineer can act on. Each layer gets a score based on its own coverage, with no help from another layer’s strengths.
Scoring prompt layer granularity: what complete coverage looks like versus what most platforms deliver
Complete prompt coverage begins with the fully rendered string sent to the model. A template reference is not the executed prompt. The platform must also preserve the originating template or instruction set, its version, and the variables injected at runtime. Those artifacts show whether the fault is in the instruction logic or an input value. The raw model output must appear with them so that intended behavior can be compared with the response.
Version tracking ties that comparison to the history of what was deployed. Without it, an engineer may look at the current template when trying to diagnose a run that used an earlier instruction set. Prompt drift after a model update also needs version-level attribution, which token counts alone cannot provide. The inspectable object is the prompt actually used, tied to its derivation and output.
Capturing the system prompt but omitting the assembled user turn leaves multi-turn failures unresolved. A hash allows deduplication but does not let an engineer inspect the content. If full text requires a separate lookup, the trace does not contain the evidence needed for review. Coverage is absent when the engineer must reconstruct the prompt from application logs outside the observability tool, slowing diagnosis and undermining reproducibility.
Scoring tool layer granularity: schema drift and silent failures as the hard cases
Consider a tool API update that renames a required field or changes its type. The agent’s prompt still refers to the old field, so calls begin failing or returning null values. A generic tool error shows where the run broke. It does not explain the mismatch. Without the schema version from the call, the engineer must manually compare the invocation with the tool’s schema to establish the cause.
Complete tool coverage preserves the full argument payload against the registered schema, the schema version at invocation, and the full response payload. A platform that compares invocation arguments with the registered schema can flag the mismatch and attribute it to the tool layer. The evidence also exposes the outdated expectation in the prompt. Attribution must explain that relationship.
An HTTP 200 response with no exception can still contain a stale value or data from the wrong scope. The value itself is the diagnostic artifact. Truncated summaries can omit the evidence needed to compare the response with expected semantics. Latency and retry counts help diagnose flakiness, but platforms recording only HTTP status and latency score absent for tool attribution under this framework.
Scoring workflow layer granularity: step sequencing, loops, and branch decisions
Workflow faults arise from how steps fit together, even when no call fails. Repeated invocations can form a loop, and steps that each succeed can still follow the wrong branch or stop too early. Each event can look valid in isolation. To diagnose these faults, an engineer needs a structured reference for how the workflow should run, including step names, branching conditions, and expected termination criteria.
Complete coverage compares how the run went with that reference. It preserves per-run invocation counts, records which branch was selected, and captures the input or model output that triggered the decision. That distinction helps show whether the fault is in the model output or the branch condition. A run-level graph or ordered step view must also expose the actual path without requiring reconstruction from a chronological event stream.
OpenTelemetry conventions provide relevant architectural background. Their request-response tracing model alone does not provide the topology needed to see how graph-structured agent execution ran. Workflow structure must be added deliberately. Repeated spans otherwise remain events rather than recognized deviations from the intended workflow. A platform that reconstructs the execution graph and flags departures from registered topology can score complete, while ordered spans alone score partial at best.
Scoring memory layer granularity: retrieval content, provenance, and cross-run persistence
Memory diagnosis begins with the content presented to the model. Complete coverage stores retrieved chunks or documents as inspectable artifacts with the generation span, rather than recording only the query and result count. It also preserves each chunk’s origin document, ingestion timestamp, and retrieval score. Provenance separates two superficially similar failures. The wrong chunk is a relevance problem, while the right chunk with outdated content is a staleness problem.
Persistent memory adds a cross-run requirement. Each entry needs a link to the run that wrote it so that an incorrect fact can be traced to its introduction. Cross-run memory diffing must also allow comparison of the state available to runs that produced different outputs. Otherwise, memory remains an unexamined variable. A retrieval trace from the current run cannot alone explain how persistent incorrect context entered the system.
This is where misattribution becomes particularly costly. The output is wrong, yet the prompt and tool calls can look correct because the defect lies in the context treated as authoritative. Adjusting the prompt or model does not address that cause. Most platforms score absent or partial here because query strings and result counts do not preserve retrieved content. Without that minimum artifact, an engineer cannot audit what the model was given.
How to apply the scoring framework across platforms in practice
The practical evaluation should use an instrumented agent workload. Construct a test agent that exercises all four layers deliberately, with a known prompt ambiguity, a tool schema that will change mid-test, a workflow loop condition, and retrieval seeded with a stale document. Run a separate failure for each layer. This shows whether the platform can trace each fault to the right layer on its own or only show that a run failed.
For each failure, inspect the artifact surfaced by the platform. The prompt test needs the rendered text and its derivation, while the tool test needs payloads and the schema in force. The workflow test needs the execution path and decision evidence, and the memory test needs the retrieved chunk and its metadata. A score or status code is insufficient. Assign absent, partial, or complete to each layer based on what the workload actually exposed.
Apply the same protocol to each candidate platform so that the comparison remains about diagnostic coverage. Dashboard screenshots are not proof of artifact capture. The displayed view may depend on manual configuration or a custom SDK wrapper that must be accounted for in the evaluation. Infrastructure strengths also need to be judged on their own because visibility into latency, error rates, and cost does not show that a platform has harness-layer attribution.
Failure-path capture deserves particular scrutiny. Happy-path traces can look complete even when artifacts are dropped or compressed when a run fails to keep storage cost down. A complete result should support a specific explanation, such as an instruction in a particular template causing a class of failures across runs, rather than a broad claim that the prompt needs improvement. That evidence becomes the starting point for a testable correction.
Where systematic trace-driven improvement picks up where observability leaves off
Attribution establishes where to intervene, but it does not validate the intervention. Finding an ambiguous instruction does not produce a better one or test it against the traces where the original failed. Following a schema mismatch diagnosis, establishing that a corrected invocation works requires replaying affected traces with the change applied, a step most observability platforms do not offer.
Workflow corrections make the distinction especially clear. A loop diagnosis can show that a termination condition was never satisfied, but a patched condition still needs testing against historical runs that looped. It must also avoid regression on runs that terminated correctly. Knowing the cause is not proof of repair. The same separation between diagnosis and validation governs changes to prompts, tool bindings, and retrieval filters.
Once production failures have been traced to their causes, the next stage should produce candidate fixes that an engineer can review. A revised prompt, corrected tool schema binding, patched workflow condition, or updated retrieval filter can then be replayed against historical failures and passing traces. The release decision belongs after that validation. Shipping only when replay shows improvement without regression turns trace evidence into a change that can be audited and avoids another production experiment.
Sources
- What Is Agent Observability? A 2026 Developer Guide
- Externalization in LLM Agents: A Unified Review of Memory, Skills, Protocols and Harness Engineering
- Harness Engineering for Predictable Agentic Systems: An Empirical Study of Deterministic Execution Constraints
- Setting Up LLM Observability Pipelines in 2026
- Agent Harness for Large Language Model Agents: A Survey[v3]
- Observability and Fault Injection for LLM-Based Multi-Agent Systems in Software Engineering
- TRAJDEBUG: Tracing Error Lifecycle to Identify Critical Failures in Long-Horizon Agent Trajectories
- Top LLM Observability Tools in 2026: A Pro Guide