Triage Protocol When Orchestration and Memory Are Both Plausible Culprits in a Live Agent Failure
Identify which layer's fingerprints appear first to pinpoint the root cause reliably.
AI agent failure attribution by harness layer requires a production trace. When orchestration and memory are both plausible culprits, identify which layer’s fingerprints appear first, then test each layer’s contribution in isolation. Assign the repair only after those tests establish causation, and validate the change against failing and historically passing traces before shipping it.
Why orchestration and memory fail in ways that look identical from the outside
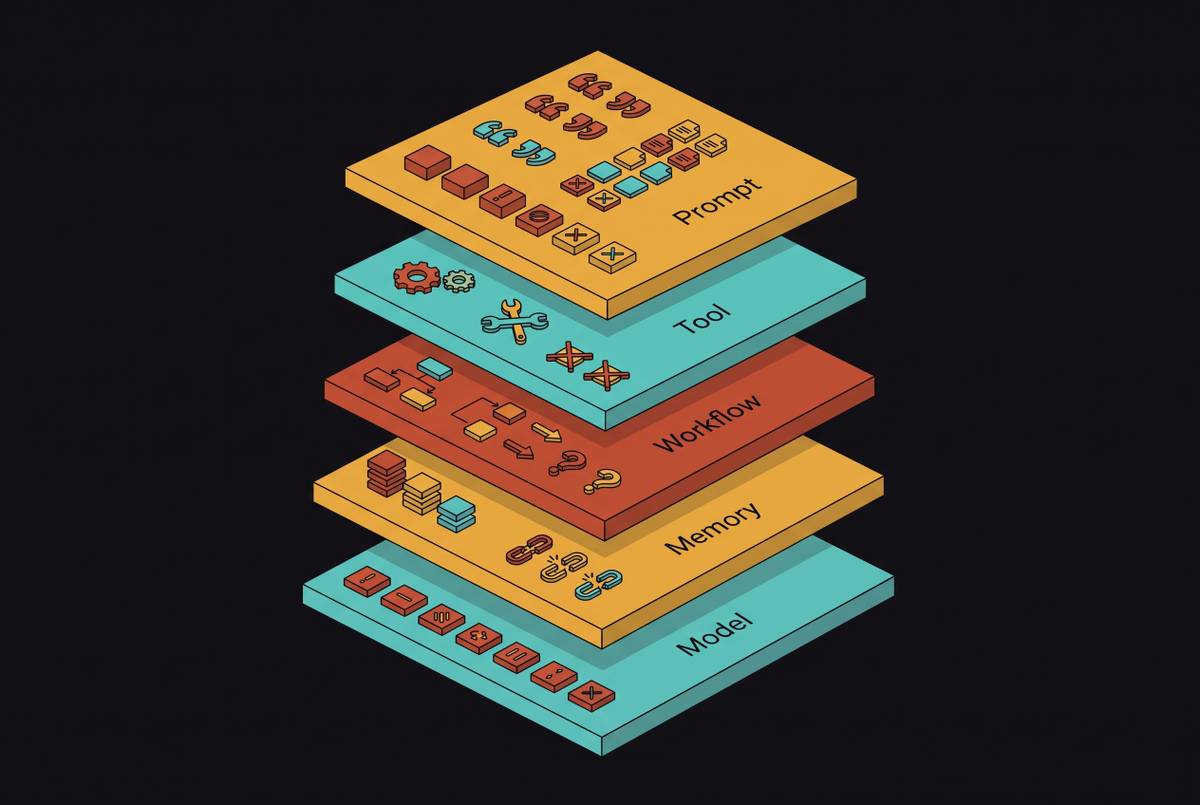
Context and Memory determines what the model sees through the context window, session state, summaries, retrieved evidence, and persistent memory. Lifecycle and Orchestration determines how the agent moves through think-act-observe loops, retries, task-state management, delegation, and termination. Yet both layers affect what the model gets at each step. Their effects converge at the same visible surface. An agent spinning on a subtask or returning a confident but wrong result does not reveal which layer created the conditions for failure.
Scale AI’s interaction-centric taxonomy illustrates the ambiguity with an earlier instruction that an agent ignores. Context compaction may have removed the instruction, or the instruction may still be present and the model may have failed to follow it. The first case needs a harness-level fix, while the second needs a model-level change. The output alone cannot distinguish these two cases. Islam et al.’s bug study adds a practical constraint, finding that agents are inherently nondeterministic and that certain bugs cannot be reproduced consistently. This makes the confusion a structural debugging problem.
How the two layers fail differently, even when symptoms overlap
Memory failures change the information available to the model. When a combined prompt goes over the token limit, some frameworks drop the oldest content without warning, while others give a metadata signal or raise an error. With silent truncation, the agent can continue producing plausible output without core instructions. A different loss occurs when relevant working memory is not promoted into episodic or semantic stores before the volatile state is discarded at session end. Retrieval can also omit critical evidence or supply information that is outdated or corrupted before it enters the context window.
Orchestration failures instead change how execution proceeds. Without an exit condition, an agent can loop or drift indefinitely, even when the information needed to stop is available. Without fallback handling, it can halt on the first tool error. Premature finalization closes a task before subtask completion has been verified. Delegation can also fail when task state is passed to a sub-agent incorrectly.
The distinction becomes useful when it directs a repair. Scale AI’s taxonomy assigns each of its 41 failure modes to an interaction edge between components and a fault side that identifies where the repair belongs. HarnessFix connects failure evidence to harness-aware diagnosis and scoped harness changes. It also identifies intertwined memory and orchestration failures as a difficult mis-attribution case. Telling these mechanisms apart helps with testing, but more than one may have been at work.
Why a trace is the only reliable starting point for triage
Traditional event logs record discrete occurrences without necessarily preserving their causal links. Span-based tracing connects model invocations, tool calls, memory reads and writes, and decision branches to their antecedents. In multi-agent workflows, a hierarchical trace also preserves the relationship between delegated work and downstream execution. That hierarchy makes propagation across sub-agents inspectable. Without it, a visible failure late in a pipeline can be mistaken for the place where the defect began.
A trace is necessary, but not self-explanatory evidence. TRAJDEBUG, from Tsinghua University and Tencent Hunyuan, identifies two obstacles to reading long trajectories. Relevant evidence can be scattered across distant steps, and local errors can have very different consequences. Some are repaired, some remain harmless, and some cause the final failure. Its approach uses multi-granularity history compression with error-lifecycle tracing to bring earlier context into view and separate whether an error was resolved from how it affected the final outcome. The critical error is therefore not necessarily the first visible mistake or the error nearest the final answer.
For practitioners, this establishes the minimum evidence base for triage. The trace must expose what the model received and how execution moved from that input to later actions. Without an inspectable trajectory, a diagnosis cannot reliably distinguish lost information from a faulty control decision.
Reading the trace for first-fingerprint evidence before attributing either layer
At the point where behavior diverges, inspect the context window for constraints and prior results that should be present. Then compare that content with the token count and the memory read/write record. A missing constraint near the token limit suggests truncation. An empty or stale retrieval suggests a different memory mechanism, even if both leave the model without the same required evidence.
The evidence for orchestration comes from records of termination and delegation. Inspect whether the termination signal fires under the conditions present in the run, and whether the sub-agent received the task state that the orchestrator recorded as passed. These fingerprints require testing to establish causation. Correct information followed by a wrong action points toward orchestration as a hypothesis, but an instruction-following failure can still belong on the model side. Missing information points toward memory, while an earlier broken handoff can explain why it was missing.
AgentRx, by Barke et al. in EMNLP Findings 2026, formalizes critical failure step localization by annotating trajectories with the first unrecoverable step and a root cause category. TRAJDEBUG adds the complementary requirement to distinguish the failure-responsible error from coexisting local mistakes. The first event that looks wrong needs to be checked, but its effect on the terminal failure still has to be shown. A later error may merely expose damage already done.
Isolating each layer’s contribution with targeted evidence tests
For the memory hypothesis, replay the trace with the suspected missing or stale content manually injected. If behavior corrects, memory is implicated. Check memory read timestamps against the version of the data that existed at execution time, rather than judging the retrieval against current data. Inspect token counts at the divergence step to confirm or rule out silent truncation. These tests separate an information deficit from an assumption that the model simply overlooked available evidence.
Inspect whether the exit condition fires under the exact conditions of the failed run or sits behind an unreachable branch. Replay with a forced early termination or with a retry suppressed, and examine whether the agent reaches a correct state. For delegated work, compare the task state received by the sub-agent with the state recorded as passed. A strong memory result does not replace these tests. The other layer may be unaffected, secondary, or independently defective.
Intertwined failures require sequential testing. A stale retrieval can return an incomplete result that the orchestrator interprets as task-not-done, prompting a retry that retrieves the same stale result. The loop then keeps repeating, with both layers playing a part in the failure. HarnessFix acknowledges mis-attribution of intertwined failures as a limitation. In this case, repair retrieval first and rerun, changing orchestration only if the loop persists.
Schema drift must also be ruled out before attribution. A downstream API can change its response shape, and a tool parser can misread it without throwing an exception. The corrupted result can look like stale memory or a model hallucination and cause symptoms in both layers. The parser is therefore part of the evidence boundary. Otherwise, tests of memory and orchestration may hide a tool-interface defect and leave it unclear what needs to be fixed.
How to attribute root cause after the evidence tests complete
Attribution is complete when at least one isolation test establishes causation and the other layer’s test has been run and found negative or secondary. The result must name the repair owner. Scale AI’s fault-side distinction captures this requirement, because identifying the interaction where a failure occurred does not establish which component needs to change. Model-side and harness-side failures at the same interaction can require different interventions.
A defensible attribution also names the mechanism precisely enough to direct work. “The model got confused” leaves the repair unassigned. Silent truncation at step 14 identifies a different target from a missing exit condition in the retry branch. The assignment should include the expected fix. HarnessFix describes this discipline as “scoped harness changes” and warns that overly broad fixes create new ways for the harness to fail.
For intertwined failures, the repair assignment remains sequential. Fix the upstream defect and validate whether the downstream symptom disappears. If the loop persists after retrieval is corrected, attribute that residual behavior separately rather than treating the first repair as a complete explanation. This preserves the distinction between an initiating defect and a second defect exposed by testing.
Validating the fix against historical traces before shipping it
Replay validation is the gate between a scoped repair and deployment. Live mode uses real tools and the real network, while replay mode uses tool responses that were recorded in a deterministic environment. This allows the repair to be tested against the failed trajectory without recreating live production conditions. The original failure is only the first check. The same change must also be tested against historically passing traces, because correcting one run does not establish that other behavior remains intact.
A truncation fix illustrates the regression risk. Removing the failure at step 14 can still disrupt cases where the prior truncation behavior was load-bearing for a different reason. Traces of past runs that passed show that trade-off before shipping. If a team responds to a wrong answer by switching models while leaving a memory or orchestration defect untouched, replay can show the replacement failing for the same reason.
Recorded responses allow comparison with the tool behavior saved in those traces, but leave other conditions on the live network untested. A replay pass therefore establishes a narrower result than universal production correctness. TRAJDEBUG’s application studies connect trace-grounded diagnoses with actionable feedback for improving downstream agent success. The practical requirement is to connect that diagnosis to a repair that passes both the failed case and the historical regression set.
What the protocol reveals about recurring failure patterns across runs
Attributing incidents over time builds a body of evidence about which layer caused each failure. If memory isolation tests establish causation in a majority of failures, the recurring retrieval mechanisms deserve structural attention. Repeated loops at the same workflow branch similarly point toward a missing or unreachable exit condition. The pattern changes the unit of engineering work. Instead of repairing apparently unrelated outputs, the team can address a recurring defect in the harness design.
Islam et al.’s study analyzed 1,187 bug-related posts and code snippets across Stack Overflow, GitHub, and Hugging Face, finding the agent core most affected by bugs, followed by tools. That finding does not establish memory as the leading cause in a particular stack. The local attribution corpus supplies that evidence. Agentic Services Computing frames continuous monitoring, auditing, and evolution of behavioral trajectories as lifecycle-native governance. With historical traces whose failures have been attributed, teams can see whether a prompt edit, tool schema update, or retrieval change alters the mix of failures before that change reaches production at scale.
Sources
- TRAJDEBUG: Tracing Error Lifecycle to Identify Critical Failures in Long-Horizon Agent Trajectories
- When Agents Fail: A Comprehensive Study of Bugs in LLM Agents with Automated Labeling
- Model or Harness? An Interaction-Centric Taxonomy for Localizing Agent Failures
- From Failed Trajectories to Reliable LLM Agents: Diagnosing and Repairing Harness Flaws
- Agentic Services Computing